Showing posts with label methylation. Show all posts

Monday, 25 November 2013

Cellular Senescence and Genome Wide Methylation Analysis

Recently we conducted a study into the pattern of methylation within senescent cells.

Senescence

Senescence is the permanent halt of proliferation associated with cellular stresses including DNA damage, damaged or short telomeres and oxidative stress.  Senescence dates back to the Hayflick limit and, while there are no definitive markers, cells typically become large and flat and can be identified by the presence of SA-β-GAL, SAHF and tumour suppression networks (i.e. p53 / p16).

Senescence is thought to be a tumour suppression mechanism, through blocking clonal proliferation of cancer cells, and a promoter of ageing via an inflammaging phenotype.  Cancer cells must somehow bypass senescence in order to continue proliferating.


Methylation 

We were interested in studying genome-wide DNA methylation patterns within senescence.  DNA methylation is the addition of a Methyl group to specific DNA bases.  In mammals this is restricted to the cytosine nucleotide (C) within DNA.  Methylation is largely localised at CpG's (a cytosine nucleotide followed by a guamine nucleotide) within the genome.

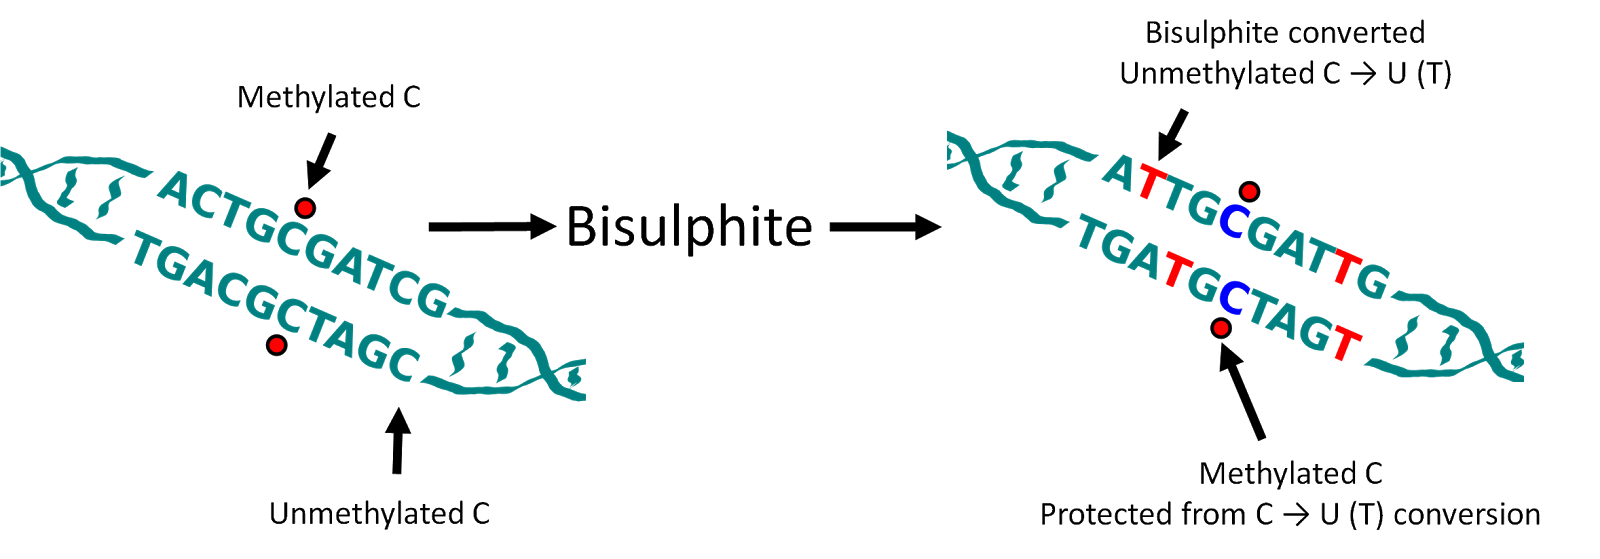
In order to study DNA methylation we use whole genome sequencing combined with bisulphite treatment.  Bisulphite treatment of DNA converts unmethylated cytosines into uracil - when we apply a process known as polymerase chain reaction (PCR) to the DNA before sequencing this is then further converted into thymine.  Methylated cytosines are unaffected.  Therefore, when sequencing a methylated cytosine will be read as a cytosine while an unmethylated cytosine will be read as a thymine.  As such when we sequence the DNA we can then deduce, via comparison with the human reference genome, which cytosine nucleotides were originally methylated and which were unmethylated.


Loss of Methylation at Late Replicating Regions

We sequenced three replicates of proliferating and replicative senescent cells (IMR90 cell culture). Our first observation was that there was a general loss of methylation (hypo-methylation) within the cells and that this loss was focused at regions of the genome which were only partially methylated (as opposed to completely unmethylated or fully methylated).  Further investigation highlighted a relationship with the regions losing methylation and late replicating regions of the genome.  i.e. regions of the genome where DNA is replicated later on during the cell cycle[1].


Focal Hypermethylation

We observed that methylation does not globally regulate gene expression changes but we did detect a subset of genes with very similar patterns in terms of methylation changes and which were coregulated at the expression level. In these genes we observed focal increase in methylation (hyper-methylation) at the regions adjacent to islands of high CpG content and that these genes were frequently associated with cell cycle functions.


Relationship to Cancer

Surprisingly, considering the role of senescence as a tumour suppression mechanism, we discovered that the methylation changes in senescence were very similar to the methylation changes that had previously been described in cancers[2,3,4].


Origins

We discovered that the origin of the loss of methylation appeared to be due to mislocalisation of the DNMT1 methyltransferase which is responsible for propagating the original methylation pattern of DNA at replication.  Specifically we noticed that foci of the DNMT1 protein are lost in old cycling cells and that these foci had previously been linked to late replicating regions[5].

Bypassing Senescence

Finally, we bypassed senescence via the introduction of SV40 T antigen into the cells in order to deactivate tumour suppression networks.  This allows the cells to continue proliferating, for a period of time, beyond the usual senescence time limit.  When we did this we made the same measurements of DNA methylation as before and found that the methylation changes that occur on the path to senescence are retained in the bypass cells.


Conclusion 

We therefore conclude that the failure of DNMT1 to methylate late replicating regions in near senescent cells may be the origin of the same methylation patterns found in cancer cells.  Furthermore, given the similarities, it may be possible that these changes may lead cells to be more susceptible to transformation into cancer cells.


The full paper is available online from Nature Cell Biology, is discussed by a CRUK press release and the raw data is available from GEO GSE48580.

References


[1] R. S. Hansen et al., Sequencing newly replicated DNA reveals widespread plasticity in human replication timing, PNAS, 2010.

[2] K. D. Hansen et al., Increased methylation variation in epigenetic domains across cancer types, Nature Genetics, 2011.

[3] B. P. Berman et al., Regions of focal DNA hypermethylation and long-range hypomethylation in colorectal cancer coincide with nuclear lamina–associated domains, Nature Genetics, 2012.

[4] G. C. Hon et al., Global DNA hypomethylation coupled to repressive chromatin domain formation and gene silencing in breast cancer. Genome Research, 2012.

[5] L. Schermelleh  et al., Dynamics of Dnmt1 interaction with the replication machinery and its role in postreplicative maintenance of DNA methylation. Nucleic Acids Res, 2007.

Tuesday, 16 July 2013

The G Test and Bisulphite Sequencing DMRs

This is Part 4 in a series on Bisulphite Sequencing.
You can return to Part 3 (Bisulphite Sequencing Simple Visualisation).


Okay, so we have our bisulphite sequencing data on the UCSC genome browser. Lets assume we have two conditions CondA and CondB, and we have two replicates of each condition. We can see what appear to be changes from our visual inspection on the browser. Now what?

Well, we probably want to compute differentially methylated regions. With 1 replicate of each that's fairly straight forward for categorical data like the bisulphite seq data we have - we use fishers exact test. With replicates a simple approach is just to pool the two replicates together and do our fishers exact test on the pooled data, but this doesn't give us a very good idea of what's going on if the two replicates disagree for a given region.

Instead we use the G-test which can be calculated for any given contingency table with the following formula:

$$$$ G = 2 \sum_{i=0}^{r} \sum_{j=0}^{c} {O_{i,j} \ln(O_{i,j}/E_{i,j}) } $$$$
Where, $$$r$$$ and $$$c$$$ are the number of rows and columns in the contingency table, $$$O_{i,j}$$$ and $$$E_{i,j}$$$ are the Observed and Expected values for cell $$$i,j$$$ in the table. I've detailed how to implement the G-test for a 2x2 contingency table in Python previously.

The main selling point of the G-test, over a regular chi-square test, is that the G value is additive. Consider the following:

G-test 1G-test 2
A B G-value
C 100 70 = 7.1
D 35 50
A B G-value
C 200 140 = 14.2
D 70 100


To find out where we have differential regions we first partition the genome into 2kb windows. There are large regions of the genome where there are no CpG's or, alternatively, where we have no sequencing coverage - we will skip those regions. We align our windows such that each window starts at an individual CpG and stops at the last CpG within 2kb of the start position.

Pooled G

We first compute a Pooled G which is the G-test performed on the pooled replicates. The contingency table would consist of columns representing each condition and rows representing methylated and unmethylated counts. The number of degrees of freedom is equal to $$$(R-1) \cdot (C-1)$$$ so as we are doing a single 2x2 contingency table this will always be equal to 1.

def pooledG(lmeth,lunmeth,rmeth,runmeth):   
    dof = 1
    pooledg = gtest(lmeth,lunmeth,rmeth,runmeth)
    return pooledg, dof, GtoP(pooledg,dof)


Total G

We then compute a G-value for each individual replicate and add them together. Each G-test we do adds 1 to the total number of degrees of freedom.

def totalG(data):
    dof = 0
    totalg = 0
    for lmeth,lunmeth,rmeth,runmeth in data:
            totalg += gtest(lmeth,lunmeth,rmeth,runmeth)
            dof+=1 
    return totalg, dof, GtoP(totalg,dof)


Heterogeneous G

If each of our three replicates reproduce exactly then Pooled G will be identical to Total G (due to the additive nature of G-test results). However, if the ratios are not identical then they will not match. The difference between the Total G-value and the Pooled G-value is the heterogeneous G-value and tells us if the difference between our replicates is significant (i.e. our replicates are not all doing the same thing.

def heterogenousG(totalg,totaldof,pooledg,pooleddof):
    heteroG = totalg-pooledg
    heterodof = totaldof-pooleddof
    return heteroG,heterodof,GtoP(heteroG,totaldof-pooleddof)


Putting it all together

Now, we can iterate through a file summarising the number of methylated and unmethylated reads at each CpG (described in a previous post) and compute the Pooled, Total and Heterogenous G-values (and corresponding p-values) for each genomic window.
import getopt
import sys
import csv
from itertools import izip_longest
from itertools import izip
from memoized import memoized

# sudo easy_install mpmath
import mpmath
#mpmath.mp.dps = 20 # decimal digits of precision

@memoized
def mpmathcdf(g,df,dps=10):
    mpmath.mp.dps = dps
    
    x,k = mpmath.mpf(g), mpmath.mpf(df)
    cdf = mpmath.gammainc(k/2, 0, x/2, regularized=True)
    
    # floating point precision insufficient, use more precision
    if cdf == 1.0:
        if dps > 4000:
            return cdf # give up after a certain point
        else:
            cdf = mpmathcdf(g,df,dps*2)
    return cdf

def GtoP(g,df):
    assert g >= 0, g
    return float(1-mpmathcdf(g,df))

import math

@memoized
def flnf(f):
    return f*math.log(f) if f>0.5 else 0

@memoized
def gtest(a,b,c,d):
    row1 = a+b
    row2 = c+d
    col1 = a+c
    col2 = b+d
    
    total = flnf(a+b+c+d)
    celltotals = flnf(a)+flnf(b)+flnf(c)+flnf(d)
    rowtotals = flnf(row1)+flnf(row2)
    coltotals = flnf(col1)+flnf(col2)
    
    # abs is necessary to account for float precision errors when doing the subtraction
    return abs(2*((celltotals + total)-(rowtotals+coltotals)))


# extract the pooled meth counts from the sample
def pooledMethCounts(data,covs,compare):
    lmethtotal = 0
    lunmethtotal = 0
    rmethtotal = 0
    runmethtotal = 0
    
    if len(compare)==2:
        # if we are given covariates to use
        covleft, covright = compare    
        for cov, (meth,unmeth) in izip(covs,grouper(2,data)): # extract in pairs of meth/unmeth
            if cov == covleft:
                lmethtotal += meth
                lunmethtotal += unmeth
            elif cov == covright:
                rmethtotal += meth
                runmethtotal += unmeth
    else:
        # if we have not been given them, assume that each adjacent sample (which is one pair) is one replicate
        for lmeth,lunmeth,rmeth,runmeth in grouper(4,data): # extract in quads (2 pairs) representing one replicate
            lmethtotal += lmeth
            lunmethtotal += lunmeth
            rmethtotal += rmeth
            runmethtotal += runmeth
        
    return lmethtotal,lunmethtotal,rmethtotal,runmethtotal


# extract individual replicate counts from the sample and return as a list of (lmeth,lunmeth,rmeth,runmeth)
# where l and r refer to the left and right cov in the compare array
# if compare array is empty assume that data is formatted as:
# lmeth1,lunmeth1,rmeth1,runmeth1,lmeth2,lunmeth2,rmeth2,runmeth2 etc
def covReplicateMethCounts(data,covs,compare):
    if len(compare)==2:
        covleft, covright = compare
        
        lreplicates = []
        rreplicates = []
    
        for cov, (meth,unmeth) in izip(covs,grouper(2,data)): # extract in pairs of meth/unmeth
            if cov == covleft:
                lreplicates.append((meth,unmeth))
            elif cov == covright:
                rreplicates.append((meth,unmeth))

        #return [(lmeth,lunmeth,rmeth,runmeth),(),(),...]    
        return [(a,b,c,d) for (a,b),(c,d) in izip(lreplicates,rreplicates)]
    else:
        # assume that each pair of samples (i.e. 4 columns) in the input is one replicate
        # in this case our input file is in the right order and we just need to split it up.
        return grouper(4,data)


# total G: at least some of the data is different
# 1 degree of freedom per replicate (i.e. 3 in total), add G's from each seperate test
def totalG(data,covs,compare):
    dof = 0
    totalg = 0
    for lmeth,lunmeth,rmeth,runmeth in covReplicateMethCounts(data,covs,compare): # extract in quads (2 pairs)
            totalg += gtest(lmeth,lunmeth,rmeth,runmeth)
            dof+=1 
    assert totalg >= 0
    return totalg, dof, GtoP(totalg,dof)

# pooled G: the data as a whole is different
# 1 degree of freedom, pool results from all replicates and do 1 2x2 table
def pooledG(data,covs,compare):    
    lmeth,lunmeth,rmeth,runmeth = pooledMethCounts(data,covs,compare)
    
    dof = 1
    
    pooledg = gtest(lmeth,lunmeth,rmeth,runmeth)
    
    assert pooledg >= 0
    
    return pooledg, dof, GtoP(pooledg,dof)

# there is evidence that they are significantly different from each other
# heterogeneity G: total G - pooled G, df = 3-1 = 2
def heterogeneityG(totalg,totaldof,pooledg,pooleddof):
    heteroG = max(totalg-pooledg,0)
    heterodof = totaldof-pooleddof
    return heteroG,heterodof,GtoP(heteroG,totaldof-pooleddof)


def grouper(n, iterable, fillvalue=None):
    "grouper(3, 'ABCDEFG', 'x') --> ABC DEF Gxx"
    args = [iter(iterable)] * n
    return izip_longest(fillvalue=fillvalue, *args)

def unpackLine(chrm,coord,*data):
    return chrm.strip(), int(coord), [int(d) for d in data]

def extractLine(line):
    chrm,coord,data = unpackLine(*line)
    if not chrm.startswith("chr"):
        chrm = "chr"+chrm
    return (chrm,coord,data)


if __name__ == '__main__':
    try:
        opts, args = getopt.getopt(sys.argv[1:], "", ["combined=","cov=","compare="])
    except getopt.GetoptError, err:
        # print help information and exit:
        print str(err) # will print something like "option -a not recognized"
        sys.exit(2)
    
    infile = None
    covs = None
    compare = None
    
    for o, a in opts:
        if o=="--combined":
            infile = a
            print "combined", a
        elif o=="--cov":
            covs = a.split(",")
            print covs
        elif o=="--compare":
            compare = a.split(",")
            print compare
            assert len(compare)==2
    
    assert infile != None
    
    # we either have compare and covs or neither
    assert compare == None or len(compare)==2
    if compare == None: assert covs == None
    if len(compare)==2: assert covs != None
    
    methfile = csv.reader(open(infile, "r"), delimiter="\t")
    
    # ---    
    # windows
    
    if compare != None:
        leftcov,rightcov = compare
        windows = csv.writer(open(infile+"."+leftcov+"-vs-"+rightcov+".windows.bedGraph","w"),delimiter='\t')
        percent = csv.writer(open(infile+"."+leftcov+"-vs-"+rightcov+".percent.windows.bedGraph","w"),delimiter='\t')
    else:
        windows = csv.writer(open(infile+".windows.bedGraph","w"),delimiter='\t')
        percent = csv.writer(open(infile+".percent.windows.bedGraph","w"),delimiter='\t')
    
    windowSize = 2000
    
    currentWindowPos = None
    currentChr = None
    
    cs = 0
    dataCount = None
    
    def writeWindow(chrm,pos,epos):
        global dataCount
        global cs
        global windows
        global percent
        
        lmethCount,lunmethCount,rmethCount,runmethCount = pooledMethCounts(dataCount,covs,compare)
        
        if (lmethCount + lunmethCount) == 0 or (rmethCount + runmethCount) == 0:
            print "Unprintable window:",chrm, pos, epos, lmethCount, lunmethCount, rmethCount, runmethCount
            return
        
        lPercentage = (float(lmethCount)/float(lmethCount+lunmethCount)) * 100.0
        rPercentage = (float(rmethCount)/float(rmethCount+runmethCount)) * 100.0
        
        total,totaldof,totalp = totalG(dataCount,covs,compare)
        pooled,pooleddof,pooledp = pooledG(dataCount,covs,compare)
        hetero,heterodof,heterop = heterogeneityG(total,totaldof,pooled,pooleddof)
        
        windows.writerow([chrm,pos,epos+1,'1' if rPercentage > lPercentage else '-1',totalp,pooledp,heterop,cs])
        
        percent.writerow([chrm,pos,epos+1,lPercentage,rPercentage])         
        
        dataCount = None
        cs = 0

    lastCoordCounted = None
    # the actual work here
    for line in methfile:
        
        chrm,coord,data = extractLine(line)

        if currentChr == None:
            currentChr = chrm
            currentWindowPos = coord
            lastCoordCounted = coord
        else:
            # always write a window if we change chrm
            if chrm != currentChr:
                writeWindow(currentChr,currentWindowPos,lastCoordCounted)
                currentChr = chrm
                currentWindowPos = coord
                
            # write a window if the next cpg is outside the current window
            elif coord - currentWindowPos > windowSize:
                writeWindow(currentChr,currentWindowPos,lastCoordCounted)
                currentChr = chrm
                currentWindowPos = coord
                
            # otherwise dont write any window (the current cpg is in the window)
        
        ####
        # add data to existing data count
        ####
        if dataCount == None:
            dataCount = data
        else:
            for index,d in enumerate(data):
                dataCount[index] += d
        lastCoordCounted = coord
        
        # inc number of c's counted
        cs += 1
        
    # after we write a window there is always at least one unmeasured coord after it so we have one more window to write
    writeWindow(currentChr,currentWindowPos,lastCoordCounted)


Note that the above script relies upon the Memoized decorator.

Executed as:

python replicatesGTest.py \
--combined "Conditions.1.and.2.CpG_context.aggregate" \
--cov Condition1,Condition2,Condition1,Condition2,Condition1,Condition2
--compare Condition1,Condition2 


Where --cov lists the order of the conditions in the file and --cov indicates which conditions should be compared.

For each window, this script outputs a tab separated file containing the chromosome,start and stop position of the window,'1' if it is "increasing" otherwise '-1' and p-values for computed from the Total, Pooled ahd Hetero G computations as well as the number of methylation sites considered in the window.

Note that the p-values generated are uncorrected for multiple testing and should be FDR corrected. I've previously described a suitable approach for large files such as these.

Differentially methylated regions can then be defined as regions of adjacent windows with a FDR adjusted p-value less than or equal to a fixed level (i.e. 0.05 FDR) that change in the same direction.

Monday, 8 July 2013

Bisulphite Sequencing Simple Visualisation (Multiple Samples)

This is Part 3 in a series on Bisulphite Sequencing.
You can return to Part 2 (Using the Binomial Distribution in Bisulphite Sequencing).
or skip to Part 4 (The G Test and Bisulphite Sequencing DMRs).


Jumping back to bisulphite sequencing analysis for a bit.  After we have summarised our data by individual CpG we probably want to do something useful with it.

First up, lets just display it on the UCSC genome browser.  When we display bisulphite sequening data on UCSC we probably want something like this below:


We also want to filter out low confidence CpGs (those with less than a certain number of reads). bismarkToBedGraph does something pretty much like this.

However, it is important that when we filter a particular CpG from any given sample we should also filter it from the other samples displayed at the same time - otherwise we give a misleading indication that there is 0% methylation in the filtered sample and a non-negative amount of methylation in the unfiltered sample.

To address this I made a short script that can take multiple replicates/samples of bisulphite sequencing data, summarised by individual CpGs, and output bedGraph files such that the same CpGs are always reported based on coverage.

import getopt
import sys
import csv
from itertools import izip_longest

class CommentException(Exception):
    pass

def grouper(n, iterable, fillvalue=None):
    "grouper(3, 'ABCDEFG', 'x') --> ABC DEF Gxx"
    args = [iter(iterable)] * n
    return izip_longest(fillvalue=fillvalue, *args)

def unpackLine(chrm,coord,*data):
    return chrm.strip(), int(coord), [int(d) for d in data]

def extractLine(line):
    if line[0].startswith("#"):
        raise CommentException()
    chrm,coord,data = unpackLine(*line)

    if not chrm.startswith("chr"):
        chrm = "chr"+chrm
    return (chrm,coord,data)
    
if __name__ == '__main__':
    try:
        opts, args = getopt.getopt(sys.argv[1:], "", ["combined=","suffixes="])
    except getopt.GetoptError, err:
        # print help information and exit:
        print str(err) # will print something like "option -a not recognized"
        sys.exit(2)
    
    infile = None
    suffixes = None
    rightsuffix = None
    
    for o, a in opts:
        if o=="--combined":
            infile = a
            print "combined", a
        elif o=="--suffixes":
            suffixes = a.split(",")
            print "Suffix", suffixes

    
    assert infile != None
    assert suffixes != None
    
    methfile = csv.reader(open(infile, "r"), delimiter="\t")
    
    files = {}
    
    for suffix in suffixes:
        percentage = csv.writer(open(infile+"-"+suffix+".percent.bedGraph","w"),delimiter='\t')
        coverage = csv.writer(open(infile+"-"+suffix+".coverage.bedGraph","w"),delimiter='\t')
        files[suffix]=(percentage,coverage)
    
    # ---
    # for each
    # coverage
    # percentage
    
    minReadsForPercentage = 5
    minSamplesWithCoverage = 1

    for line in methfile:
        try:
            (chrm,coord,data) = extractLine(line)
        except CommentException:
            continue
        
        percentages = []
        coverages = []
        
        for meth,unmeth in grouper(2,data):
            coverage = meth + unmeth
            if coverage == 0:
                percentage = 0
            else:           
                percentage = (float(meth)/float(meth+unmeth)) * 100.0
            percentages.append(percentage)
            coverages.append(coverage)
    
        satisfycoveragecriteria = 0
        for coverage in coverages:
            if coverage >= minReadsForPercentage:
                satisfycoveragecriteria += 1
        if satisfycoveragecriteria < minSamplesWithCoverage:
            continue

        for index,(percentage,coverage) in enumerate(izip_longest(percentages,coverages)):
            
            percentfile,coveragefile = files[suffixes[index]]
            percentfile.writerow([chrm,coord,coord+1,percentage])
            coveragefile.writerow([chrm,coord,coord+1,coverage])
            

Executed as:

python bisulphiteToBedGraph.py \
--combined "Samples.1.and.2.CpG_context.aggregate" \
--suffixes Sample1,Sample2,Sample3,Sample4 

You can then use bedGraphToBigWig to create bigWig files suitable for UCSC custom track / track hubs.

Thursday, 7 February 2013

Post-Processing Bismark Bisulphite Sequencing Data

This is Part 1 in a series on Bisulphite Sequencing.
You can skip to Part 2 (Using the Binomial Distribution in Bisulphite Sequencing)
.


In this post I will present a couple of scripts that are useful for processing the data produced by the Bismark bisulphite sequencing aligner into a form that is a little easier to work with.

When you run Bismark it will produce output in either its own "vanilla" format (version <= 0.5x) or in SAM format (version >= 0.6x).

Either way, the approach at this point is to remove duplicate reads that might have occurred as PCR duplicates using deduplicate_bismark_alignment_output.  I usually also remove any fragments which look like they haven't been bisulphite converted (multiple apparently methylated CHH or CHG within a single fragment).

For Bismark vanilla output you can use something like this:

awk 'FNR>1{
      countl = split($8,a,"[HX]");
      countr = split($11,a,"[HX]");
      if (countl-1 <= 3 && countr-1 <= 3)
           print;
     }' $file > $file.unconvertedreadsremoved

(Where the 8th and 11th columns contain the methylation call string in Bismark format).

Next up is to extract the methylation calls for each base using the methylation_extractor script (included with Bismark) using the --no_overlap and --comprehensive options.

This will give you a file that looks a little like this:

FCD0KMMACXX:3:1101:17551:2000#CTTCCTCC/1    +    chr3    116402006    Z
FCD0KMMACXX:3:1101:17551:2000#CTTCCTCC/1    +    chr3    116401980    Z
FCD0KMMACXX:3:1101:17551:2000#CTTCCTCC/1    +    chr3    116401960    Z
FCD0KMMACXX:3:1101:17865:1999#CTTCCTCC/1    -    chrX    115417650    z
FCD0KMMACXX:3:1101:18710:1999#CTTCCTCC/1    -    chr15    51474193    z
FCD0KMMACXX:3:1101:18710:1999#CTTCCTCC/1    +    chr15    51474352    Z
FCD0KMMACXX:3:1101:18599:2000#CTTCCTCC/1    +    chr3    101217644    Z

First we make it a little easier by sorting by chromosome and base position such that all the methylation calls for the same base are together as well as removing the Bismark header line.

awk 'FNR>1' CpG_context.txt | \
sort -k3,3 -k4,4n -S10G > CpG_context.sorted.txt

Again, as in the previous post, you can control sorts memory usage using the -S flag (set to 10G above). We can then sum up (aggregate) the file on a per CpG basis.

import getopt
import sys
import csv

def parseMethLine(line):
    (readid,meth,chrm,coord,methcall) = line
    return (True if meth == '+' else False, chrm, coord)

if __name__ == '__main__':
    try:
        opts, args = getopt.getopt(sys.argv[1:], "",
                                  ["bismark=", "aggregate="])
    except getopt.GetoptError, err:
        # print help information and exit
        # will print something like "option -a not recognized"
        print str(err) 
        sys.exit(2)
    
    infile = None
    aggregatefile= None
    
    for o, a in opts:
        if o=="--bismark":
            infile = a
            print "Bismark", a
        elif o=="--aggregate":
            aggregatefile = a
            print "Aggregate", a
    
    assert infile != None
    assert aggregatefile != None
    
    bismark = csv.reader(open(infile, "r"), delimiter="\t")
    
    aggregate = csv.writer(open(aggregatefile,"w"),delimiter='\t')      
    
    currentchrm = None
    currentpos = None
    
    methylated = 0
    unmethylated = 0
    
    for line in bismark:
        (methcall, chrm, coord) = parseMethLine(line)
        
        # meth calls in 1 base, ucsc / bedgraph in 0 base
        coord = int(coord) -1 
        
        # init
        if currentpos == None or chrm == None:
            currentchrm = chrm
            currentpos = coord
        elif currentpos != coord or currentchrm != chrm:
            # a new position or chromosome encountered
            # output our counts until now
            aggregate.writerow([currentchrm,currentpos,
                                methylated,unmethylated])
            
            # reset counts for next position
            currentchrm = chrm
            currentpos = coord
            methylated = 0
            unmethylated = 0
        
        if methcall:
            methylated += 1
        else:
            unmethylated += 1
    
    # output last line
    aggregate.writerow([currentchrm,currentpos,
                        methylated,unmethylated])

Executed as:

python aggregateBismark.py \
--bismark "CpG_context.sorted.txt" \
--aggregate "CpG_context.aggregate"

This will produce a file that's a little more useful.  Each CpG is represented by a single line with two data columns indicating the number of methylated and unmethylated calls made for that base (3rd and 4th columns respectively).

In other words we will have a file that looks like this:

chr1    1343    1    0
chr1    1625    4    0
chr1    1626    1    0
chr1    1655    1    0
chr1    1689    2    1
chr1    1690    2    0

Since we probably have more than one sample that we will want to be able to compare with each other we will want to combine two (or more) of the aggregate files above.  The script below will combine any two files with chromosome and coordinate as the first columns which are sorted the same way.

import getopt
import sys
import csv

if __name__ == '__main__':
    try:
        opts, args = getopt.getopt(sys.argv[1:], "",
                                  ["one=", "two=", "combine="])
    except getopt.GetoptError, err:
        # print help information and exit
        # will print something like "option -a not recognized"
        print str(err) 
        sys.exit(2)
    
    oneloc = None
    twoloc = None
    combineloc = None 
    
    for o, a in opts:
        if o=="--one":
            oneloc = a
            print "One", a
        elif o=="--two":
            twoloc = a
            print "Two", a
        elif o=="--combine":
            combineloc = a
            print "Combine", a
    
    assert oneloc != None
    assert twoloc != None
    assert combineloc != None
    
    left = csv.reader(open(oneloc, "r"), delimiter="\t")
    right = csv.reader(open(twoloc, "r"), delimiter="\t")
    
    combine = csv.writer(open(combineloc,"w"),delimiter='\t')      
    
    def unpackLine(chrm,coord,*data):
        return chrm.strip(), int(coord), [int(d) for d in data]
    
    def extractLine(line):
        chrm,coord,data = unpackLine(*line)
        if not chrm.startswith("chr"):
            chrm = "chr"+chrm
        return (chrm,coord,data)
    
    # get the first data points
    
    lchr,lcoord,ldata = extractLine(left.next())
    rchr,rcoord,rdata = extractLine(right.next())
    
    # find out how many data columns in each object
    # first line will tell us
    leftcols = len(ldata)
    rightcols = len(rdata)
    
    leftFinished = False
    rightFinished = False
    
    
    def spoolBoth():
        global lchr,lcoord,ldata,leftFinished
        global rchr,rcoord,rdata,rightFinished
        
        row = [lchr,lcoord]
        row.extend(ldata)
        row.extend(rdata)        
        combine.writerow(row)
        
        try:    
            lchr,lcoord,ldata = extractLine(left.next())
        except StopIteration:
            leftFinished = True    
        try:            
            rchr,rcoord,rdata = extractLine(right.next())
        except StopIteration:
            rightFinished = True 
        
    def spoolLeft():
        global lchr,lcoord,ldata,leftFinished
        
        rdata = [0 for i in range(0,rightcols)]
        
        row = [lchr,lcoord]
        row.extend(ldata)
        row.extend(rdata)        
        combine.writerow(row)
        
        try:    
            lchr,lcoord,ldata = extractLine(left.next())
        except StopIteration:
            leftFinished = True          
    
    def spoolRight():
        global rchr,rcoord,rdata,rightFinished
        
        ldata = [0 for i in range(0,leftcols)]
        
        row = [rchr,rcoord]
        row.extend(ldata)
        row.extend(rdata)
        combine.writerow(row)
        
        try:            
            rchr,rcoord,rdata = extractLine(right.next())
        except StopIteration:
            rightFinished = True    
    
    while not leftFinished or not rightFinished:
   
        if leftFinished:
            spoolRight()
        elif rightFinished:
            spoolLeft()
        else:
            if lchr == rchr and lcoord == rcoord:
                # we have a match, print it and spool both
                spoolBoth()
            elif lchr < rchr:
                spoolLeft()
            elif lchr > rchr:
                spoolRight()   
            # we are on the same chromosome
            # but we have skipped one (or more) position
            elif lcoord < rcoord:
                spoolLeft()
            else:
                spoolRight()

Execute this as follows:

python combineAggregate.py \
--one "Sample1.CpG_context.aggregate" \
--two "Sample2.CpG_context.aggregate" \
--combine "Samples.1.and.2.CpG_context.aggregate"


Ultimately you'll be left with a file where each CpG (or CHH, CHG) is a single line. A pair of columns represents the number of methylated and unmethylated calls in one sample and multiple pairs indicate multiple samples. Giving you something that looks like this.
chr1    1343    1    0    2    0
chr1    1625    4    0    5    3
chr1    1626    1    0    1    0
chr1    1655    1    0    1    5
chr1    1689    2    1    2    1
chr1    1690    2    0    3    1

I find this file format much easier to deal with for further downstream analysis. Once you've combined Sample 1 and Sample 2 you can then take the output and combine that with Sample 3 and so on.